Word Break
Given a string Note:
note that the same word in the dictionary may be reused multiple times in the segmentation.
swordDicttrues
Example 1
Output: true
Explanation: "codecs" can be made using the words from dictionary.
Example 2
Output: true
Explanation: "applepenapple" can be made using "apple" and "pen" words from dictions and we have to use "pen" word two times and we are allowed to use as per problem statement.
Example 3
Output: false
Explanation:"catsandog" cannot be made using the words from dictionary.
Contents
Solution 1 - using brute force approach
In this approach, we will start with every word from wordDicts
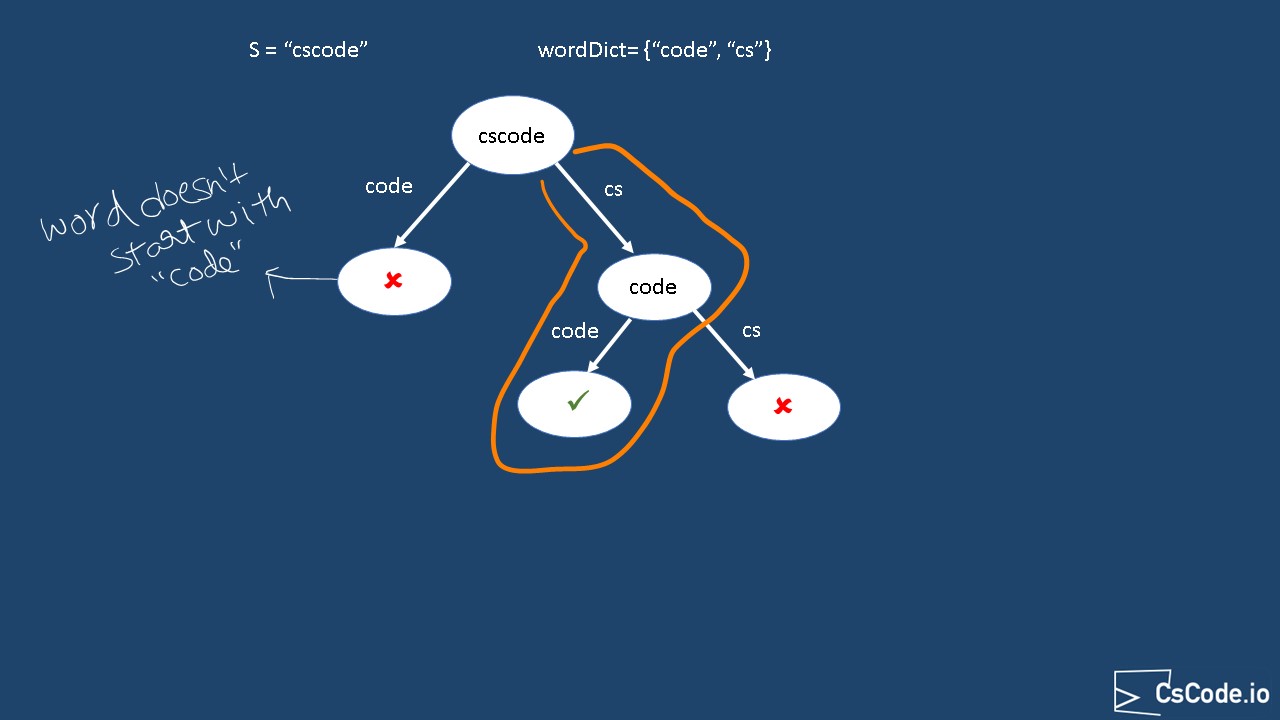
Say for example if the input string given is "cscode" and word dictionary is {"code", "cs"}
-
We start with 1st word
"code""cscode" -
Then we start with 2nd word
"cs""cscode"-
Again we start with 1st word
"code""code"
-
Again we start with 1st word
If we look at the decision tree for all possible combinations, it will look like below diagram.
-
We will create a function
bruteForceApproachswordDict -
Base cases are:
-
If the input string's length is 0, return
truewordDict
-
If the input string's length is 0, return
-
For every word in
wordDicts-
If the target string starts with the word, then take the remainder substring and call
bruteForceApproach -
If the target string doesn't start with the word, return
false
-
If the target string starts with the word, then take the remainder substring and call
public class WordBreak {

    /* brute force approach*/
    static boolean bruteForceApproach(String s, String[] wordDict) {

        if(s.length()==0){
            return true;
        }

        for(String word: wordDict) {
            if(s.indexOf(word) == 0) { // if the string starts with the word
                String remainder = s.substring(word.length());
                if(bruteForceApproach(remainder, wordDict)) {
                    return true; // possible to construct the string using words from wordDict
                }
            }
        }

        return false;
    }

}
Complexity Analysis:
Time complexity: Above code runs in O(nm * m) time where nwordDictms
The height of the decision will be mnmsubstring
Space complexity: O(m2) since we calling the function recursively, this is memory used for
remainder substring and number of recursive calls in the stack.
Note: In the above implementation, we have created substrings using the indexes for easiness of understanding, but when we call the function recursively we could also pass starting index as parameter and avoid creating substrings, in that case space complexity will be O(nm).
Solution 2 - using DP memoization
From the above brute force approach, we can notice that there are some overlapping problems.
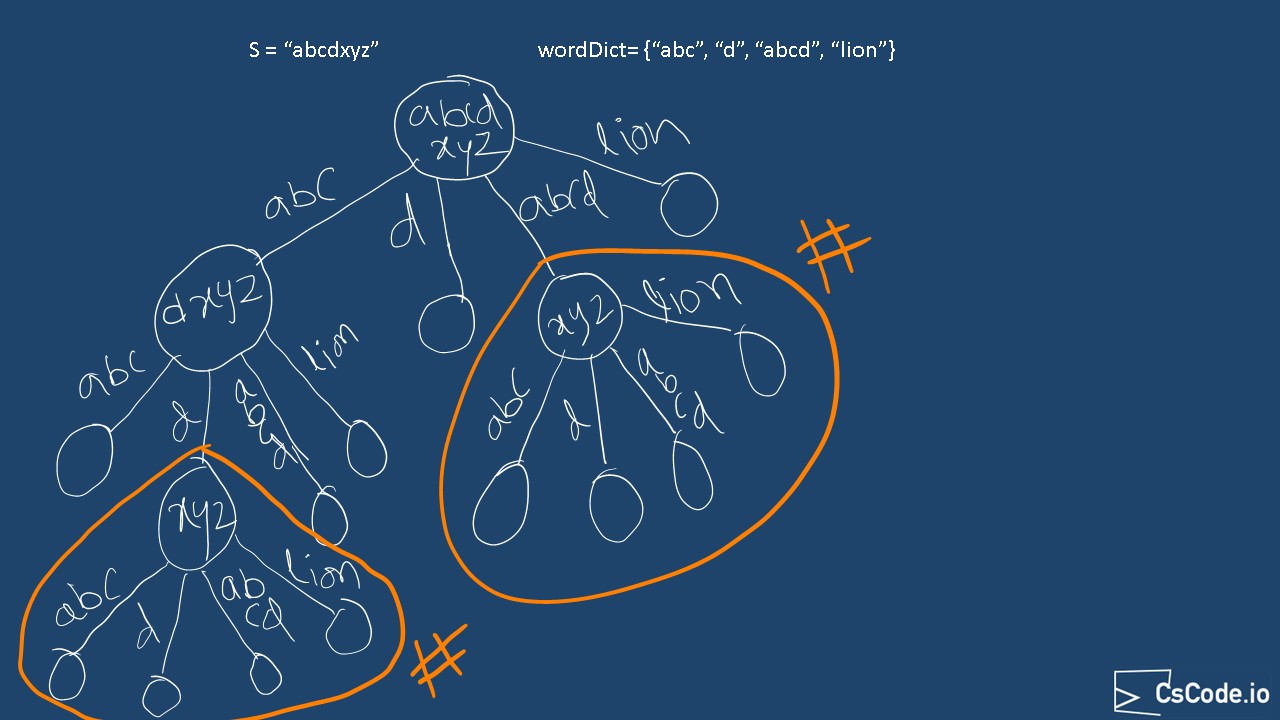
For example, consider target s = "abcdxyz"wordDict = {"abc", "d", "abcd", "lion"}
-
If we construct a decision tree to see the possibilities whether the string can be made using the dictionary of words
, it looks like below diagram and as you can see highlighted sub problems are overlapping.
-
So, in this approach, we will be caching sub problem result into a
HashMap
import java.util.HashMap;

public class WordBreak {

    /* DP memoization approach */
    static boolean dpMemoizationApproach(String s, String[] wordDict) {
        HashMap<String, Boolean> cache = new HashMap<>();
        return dpMemoizationApproachRec(s, wordDict, cache);
    }

    static boolean dpMemoizationApproachRec(String s, String[] wordDict, HashMap<String, Boolean> cache) {

        if(s.length() == 0) {
            return true;
        }

        if(cache.containsKey(s)) {
            return cache.get(s);
        }

        for( String word: wordDict) {
            if(s.indexOf(word) == 0) {
                String remainder = s.substring(word.length());
                if (dpMemoizationApproachRec(remainder, wordDict, cache)) {
                    cache.put(remainder, true);
                    return true;
                }
            }
        }
        cache.put(s, false);
        return false;
    }

}
Complexity Analysis:
Time complexity: Above code runs in O(n * m2) time where nwordDictms
Space complexity: O(m2) for the cache we are maintaining (m) , stack for recursive calls and the substring operation (m * m).
Solution 3 - using DP Bottom-Up approach using tabulation and memory optimized
In this approach we will look at solving the problem using dynamic programming using tabulation caching mechanism.
In this solution, we are going to create a temporary array with size as m + 1mi
-
To start with, at the right end of cache, we will store
trueswordDict -
Then, for each letter from right to left, check if that substring exists in the
wordDictcache[i] = cache [i + length(word)];s = "abcd"wordDict = {"ab", "cd"}- We start with cache as [false, false, false, false, true]
- When i= 3, neither of words "ab" or "cd" can fit from this index.
-
When i= 2, word "cd" can fit from this index. So, we update the cache:
cache[3] = cache[3 + length("cd")]; = cache[3+2]; = cache[5]; - When i= 1, neither of words "ab" or "cd" can fit from this index.
-
When i= 0, word "ab" can fit from this index. So, we update the cache:
cache[0] = cache[0 + length("ab")]; = cache[2]; -
Finally we will return the value at 0th index. So, our answer will be
true
public class WordBreak {

    /* DP tabulation memory optimized */
    static boolean dpTabulationMemoryOptimized(String s, String[] wordDict) {
        boolean[] cache = new boolean[s.length()+1];
        cache[s.length()] = true; // if we reach the end of input target string, that means string "s"
                                    // can be constructed using words from wordDict.
        for (int i=s.length()-1; i>=0; i--) {
            for(String word : wordDict) {
                if(i+ word.length() <= s.length() && word.equals(s.substring(i, i+word.length()))) { // i+ word.length() <= s.length() =>
                                                    // to check if "s" has enough characters to check
                    cache[i] = cache[i + word.length()];
                }
                if(cache[i] == true) { // we have found a matching word
                    break;
                }
            }
        }

        return cache[0];
    }

}
Complexity Analysis:
Time complexity: Above code runs in O(n * m2) time where nwordDictms
Space complexity: O(m) for the cache we are maintaining that is of input string length.
Above implementations source code can be found at