Decode Ways
A message containing letters from A-Z
    'A' -> '1'
    'B' -> '2'
    'C' -> '3'
    ...
    ...
'Z' -> '26'"11106"
-
"AAJF"(1 1 10 6) -
"KJF"(11 10 6)
(1 11 06)"06"'F'"6""06"
Given a string s
Example 1
Output: 2
Explanation: "12" can be decoded as "AB" with mapping as 1->A and 2->B or "L" with mapping as 12->L.
Example 2
Output: 3
Explanation: "226" can be decoded as "BBF" with mapping as 2->B, 2->B and 6->F or "VF" with mapping as 22->V and 6->F or "BZ" with maping as 2->B and 26->Z.
Example 3
Output: 0
Explanation: "06" cannot be mapped to "F" because of the leading 0, if it was just 6 then it can be mapped to "F".
Contents
Solution 1 - using brute force approach
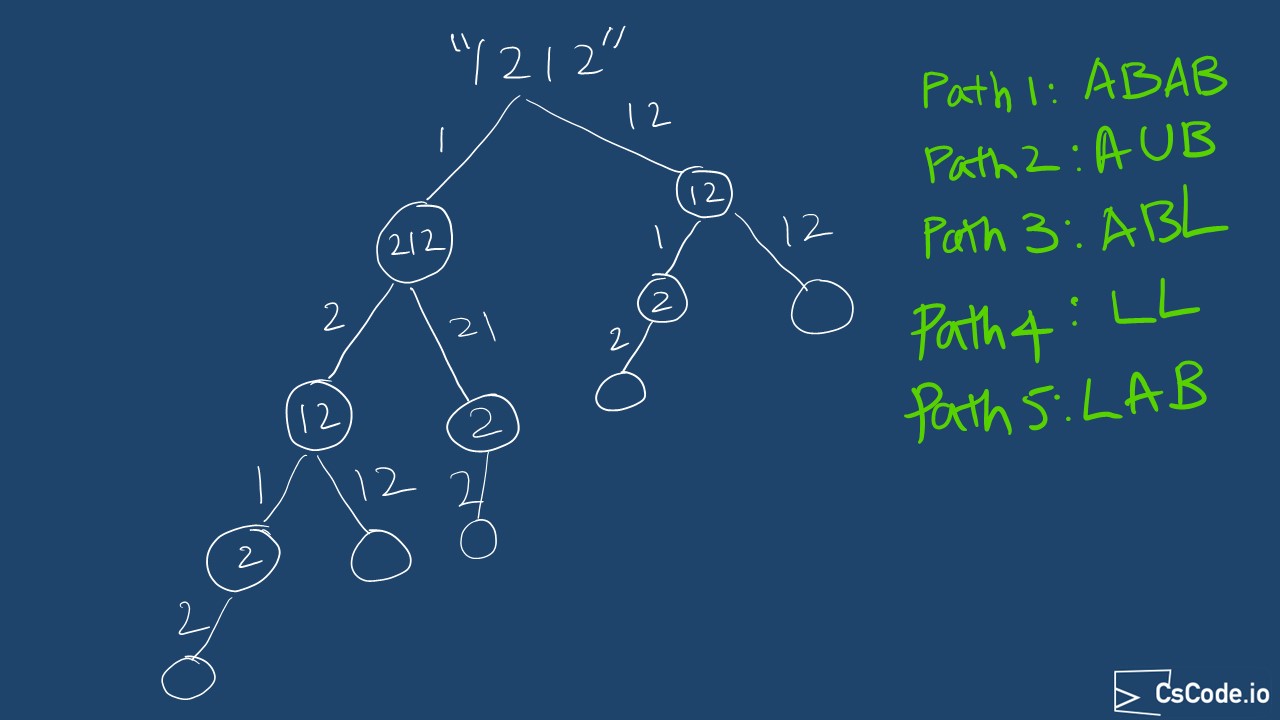
In this approach, we will generate all possible ways to decode the given input string. From every starting index of string we look at 1st indexed character and if it is valid, that is it should be a non zero character and 1st and 2nd characters together and if it is valid, that is it should be within the boundaries of two digit possible letters 10-26 (J-Z).
Say for example if the input string is "1212", you can see that from 1st digit '1'A'12'L
-
We will create a function
bruteForceApproachs -
Base cases are:
-
If the input string is
null'0'0 -
If the input string length is
011
-
If the input string is
-
Take the 1st character of the string, since it is a valid letter. For the remainder of string call the function
bruteForceApproach -
Then, check if we can take first two characters together and decode it, that means first two characters should be within the boundaries of 10-26.
We can take them if one of below conditions are satisfied.
-
If the 1st character is
'1' -
If the 1st character is
'2''0''6'
-
If the 1st character is
-
If we are considering first two characters, then call the function
bruteForceApproach
public class DecodeWays {

    /* brute force approach solution */
    static int bruteForceApproach(String s) {
        if(s == null || s.startsWith("0")){
            return 0;
        }

        if(s.length() == 0 || s.length() ==1) {
            return 1;
        }

        String first_char_remainder = s.substring(1);
        int result = bruteForceApproach(first_char_remainder); // recursively call for remaining substring after 1st character
        char char_1 = s.charAt(0);
        char char_2 = s.charAt(1);
        if(char_1 == '1'
                || (char_1=='2' && (char_2=='0' || char_2 == '1' || char_2 =='2' || char_2 =='3'
                                    || char_2 == '4' || char_2 == '5' || char_2 == '6'))) {
            String second_char_remainder = s.substring(2);
            result+= bruteForceApproach(second_char_remainder);
        }
        return result;
    }

}
Complexity Analysis:
Time complexity: Above code runs in O(2n) time where n
Space complexity: O(n) since we calling the function recursively, this is the stack memory.
Note: In the above implementation, we have created substrings using the indexes for easiness of understanding, but when we call the function recursively we could also pass starting index as parameter and avoid creating substrings.
Solution 2 - using DP memoization
From the above brute force approach, we can notice that there are some overlapping problems, such as sub problem with node
-
If we look at the decision tree diagram from above brute force aproach, highlighted sub problems are overlapping.
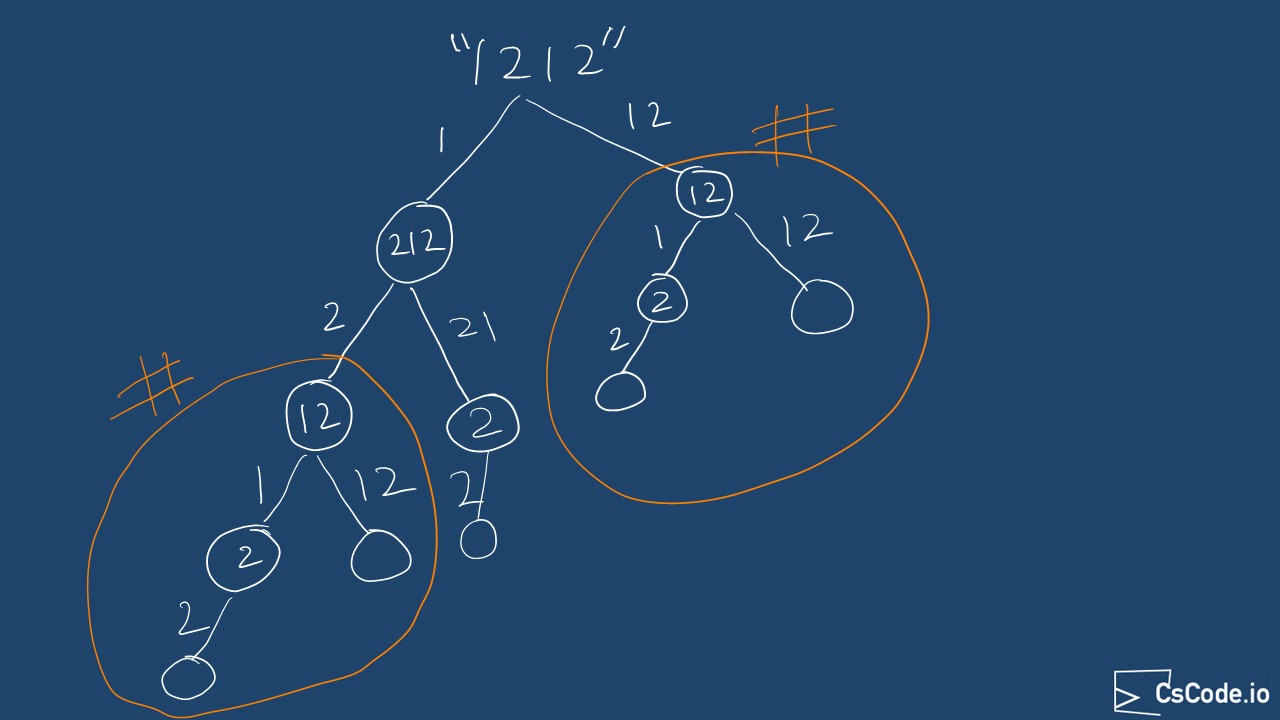
-
So, in this approach, we will be caching sub problem result into a
HashMaps
import java.util.HashMap;

public class DecodeWays {

    /* DP memoize solution */
    static int dpMemoizeApproach(String s) {
        HashMap<String, Integer> cache = new HashMap<>();
        return dpMemoizeApproachRec(s, cache);
    }
    static int dpMemoizeApproachRec(String s, HashMap<String, Integer> cache) {
        if(s == null || s.startsWith("0")){
            return 0;
        }

        if(s.length() == 0 || s.length() ==1) {
            return 1;
        }

        if(cache.containsKey(s)) { // re-use cached result if it exists
            return cache.get(s);
        }

        String first_char_remainder = s.substring(1);
        int result = bruteForceApproach(first_char_remainder); // recursively call for remaining substring after 1st character
        char char_1 = s.charAt(0);
        char char_2 = s.charAt(1);
        if(char_1 == '1'
                || (char_1=='2' && (char_2=='0' || char_2 == '1' || char_2 =='2' || char_2 =='3'
                                    || char_2 == '4' || char_2 == '5' || char_2 == '6'))) {
            String second_char_remainder = s.substring(2);
            result+= bruteForceApproach(second_char_remainder);
        }
        cache.put(s, result); // cache result
        return result;
    }

}
Complexity Analysis:
Time complexity: Above code runs in O(n) time where ns
Space complexity: O(n) for the cache we are maintaining and stack for recursive calls.
Solution 3 - using DP Bottom-Up approach using tabulation
In this approach we will look at solving the problem using Dynamic programming using tabulation caching mechanism.
The time and memory complexity will be same as above solution using memoization,
but we can notice a pattern to improve memory complexity to constant in later solution.
In this solution, we are going to create a temporary array to cache the possible ways to decode at current index, and for the next subsequent index possibilities, use the cache built so far and continue exploring number of ways to decode. The main intution in this solution is:
-
When we are at index
i1 or above1-9cache[i]cache[i-1]
The reason why we do this is because when decoding is possible at current index element, then we need to update the cache at current index to indicate that decoding can continued to current index.Javacache[i] += cache[i-1]; -
Now, we also need to check whether decoding with two digits is possible or not. i.e. with previous element and current element.
If the previous value is
120-6i-2
cache[i] += cache[i-2];Note:
When we create cache array in below solution, we initialize array with n+1ii1-910-26n+11
Consider an example with input string "1212":
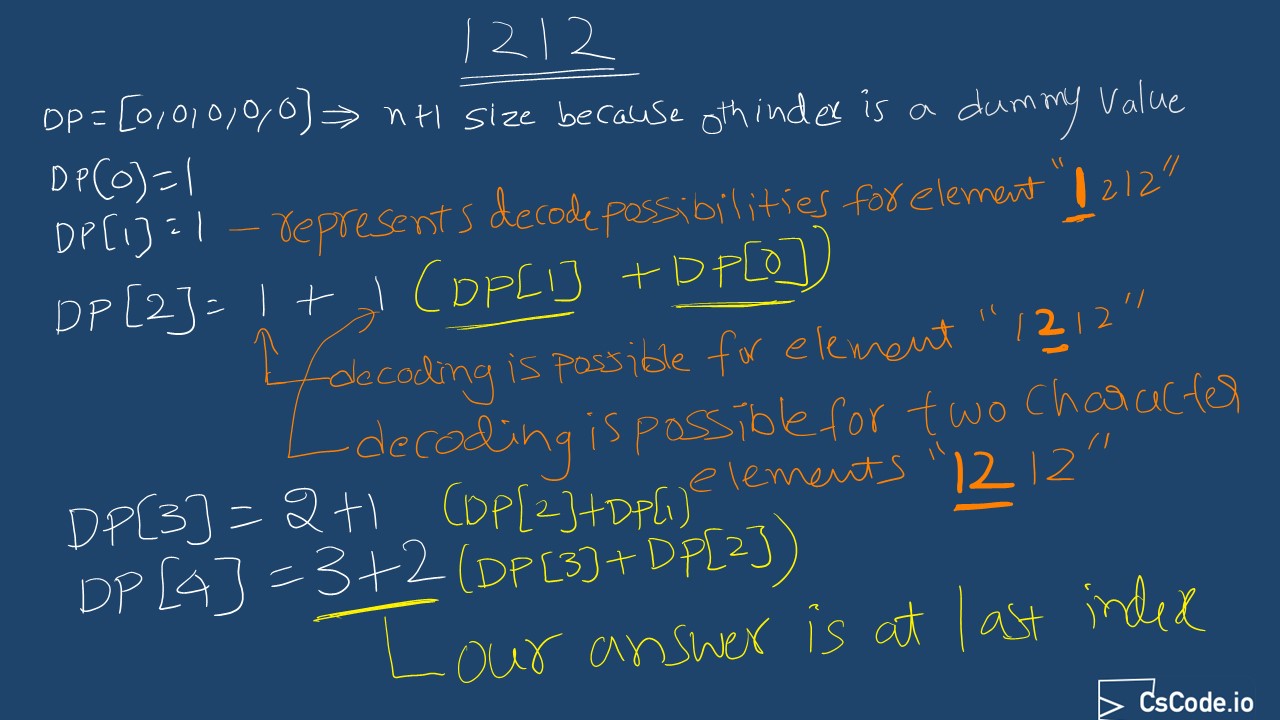
public class DecodeWays {

  /* DP tabulation approach */
  static int dpTabulationApproach(String s) {
      if(s.charAt(0) == '0') {
          return 0;
      }
      int[] count = new int[s.length()+1];
      count[0] = 1; // dummy value
      count[1] = 1; //decode possibilities for 0th index element from input string
      for(int i=2; i<=s.length(); i++) {

          int current = s.charAt(i-1); // though we are at i=2, we have to continue from 1st index of input string
          int prev = s.charAt(i-2);

          if(current > '0'){ // It does ascii comparison, but this is fine as ASCII values for 1 -9 will be greater than ASCII of 0
              count[i] += count[i-1];
          }
          if(prev =='1' ||
                  (prev == '2' && (current =='0' || current == '1' || current == '2' || current == '3'
                                  || current == '4' || current =='5' || current =='6'))) {
              count[i] += count[i-2];
          }
      }
      // finally take the last element of DP tabulation array
      return count[s.length()];
  }

}
Complexity Analysis:
Time complexity: Above code runs in O(n) time where ns
Space complexity: O(n) for the cache we are maintaining.
Solution 4 - using DP Bottom-Up approach memory optimized
If you observe above solution DP using tabulation we are maintaining a temporary array with size n+1i
public class DecodeWays {

  /* DP memory optimized */
  static int doMemoryOptimized(String s) {
      if(s.charAt(0) == '0') {
          return 0;
      }
      int prev = 1;
      int current = 1;
      for(int i=2; i<=s.length(); i++) {

          int one_char = s.charAt(i-1);
          int two_char = s.charAt(i-2);

          int temp = 0;
          if(one_char > '0'){
              temp += current;
          }
          if(two_char =='1' ||
                  (two_char == '2' && (one_char =='0' || one_char == '1' || one_char == '2' || one_char == '3'
                          || one_char == '4' || one_char =='5' || one_char =='6'))) {
              temp += prev;
          }
          prev = current;
          current = temp;
      }
      // finally return current value
      return current;
  }

}
Complexity Analysis:
Time complexity: Above code runs in O(n) time where ns
Space complexity: O(1) since we are maintaining previous two values.
Above implementations source code can be found at